Agent improvement

The applied science factory for improving AI agents

Pavo learns how your agent behaves across traces, tools, code, user feedback, and outcomes. It builds the benchmark, finds failures, and compares interventions before a controlled rollout.

See how Pavo works

Current agent stack

prompts · tools · routing

Production traces

steps · tool calls · errors

Task outcomes

success · abandonment · feedback

Candidate interventions

prompt · tool · retrieval · model

Eval suite

built from your own traces

Staged rollout

a slice of real tasks

Task outcomes improve

Pavo learns your current agent stack, reads production traces and task outcomes together to propose prompt, tool and routing changes, scores them on an eval suite built from your own traces, stages the survivors on real tasks, and writes the measured result back.
  • Increase experimentation velocity

    Explore prompts, tools, retrieval, routing, and models in parallel. Move stronger candidates to controlled tests faster.

  • Increase release confidence

    Evaluate candidates on production-derived cases and hard cohorts. Advance only after task and regression checks.

  • Force multiplier for your team

    Automate trace analysis, eval construction, and experiment preparation.

How it works

Connect your agent stack

Connect code, prompts, tools, traces, user feedback, outcome data, evals, and experiment history.

Build system understanding

Pavo reconstructs how your production system works. Your team verifies the system book.

System bookArchitectureServices, models, pipelinesMetricsDefinitions and ownersFailure modesWhat breaks, and whenExperimentsPast runs and outcomes

Run applied science projects with Pavo

Give Pavo a task outcome and guardrails. It finds gaps, builds evals, compares interventions, and opens PRs.

Frame the problemBuild hypothesesRun interventionsEvaluate offlineLive A/B test

Capabilities

Applied science judgement

Picking the right problem, the right approach, the right lever

  • Finds where the agent is failing - which task type, which step, which user intent
  • Knows whether to fix the prompt, the tools, the retrieval, the routing, or the model
  • Grounds it in your own past traces and fixes, not just what's in the repo
TASK SUCCESS · EXAMPLE9%SUPPORTOPSSIMPLEEDGEMULTIPROMPTTOOLSSTATE UNVERIFIEDRETRIEVALROUTE/MODELVERIFY FINAL STATEFOR MULTI-STEP TASKSTest: outcome pass ratePRODUCTION TRACESPAST FIXES

Scientific rigour

Explores widely, and ships only what's proven

  • Tries prompts, tool definitions, routing and fine-tunes at once instead of one change at a time
  • You see which candidates win on an eval set built from your own traces, before it reaches users
  • Checks hard cases and regressions, not just the headline score - no fix that breaks what worked
REUSEDVERIFY FINAL STATEFOR MULTI-STEP TASKSTRACE REPLAYGRADERS CALIBRATEDREGRESSION CHECKS301031PROMPTTOOLSRETRIEVALROUTINGMODELSIMPLEEDGEMULTIPROMPT V2TOOL SCHEMA V3GUARDED TOOL ROUTERSELECTEDOUTCOME-AWARE ROUTEREXAMPLE · READY TO TEST

Knowledge compounds

Every iteration makes the next one cheaper

  • The work itself produces new knowledge - how users actually phrase things, which failures cluster, which fixes don't generalise
  • Written back to your system book, reviewed by your team, reused next time - it stays with you
  • Your team owns the learnings, so v2 to v3 to v4 gets faster, not just further
01LEARN02RETAIN03REUSEOutcome-aware routerEXAMPLE · TESTEDFinal text can mask failureTool errors cluster by taskPrompt fix does not generaliseYOUR SYSTEM BOOKTASK PATTERNSGRADER CALIBRATIONFIX HISTORYTIME TO PROOF · EXAMPLE4wV23wV31wV4KNOWLEDGE REUSED

Use-cases

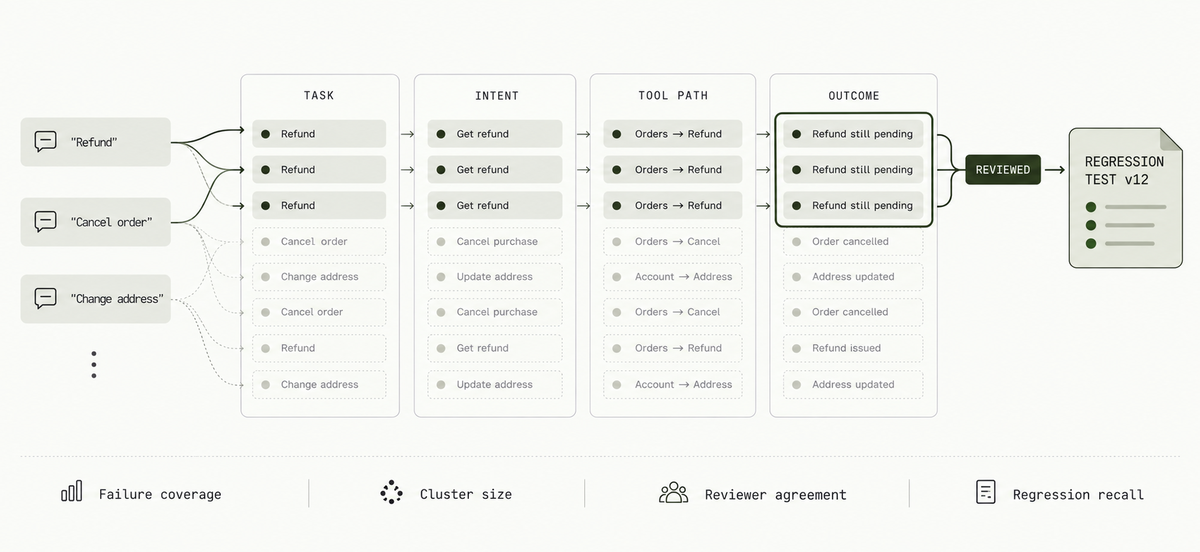
Illustrative marketplace-support traces grouped by task, intent, tool path, and outcome; a recurring refund failure becomes reviewed regression test version 12.

Our eval suite misses the failures users keep finding in production

Pavo groups traces by task, intent, tool path, and outcome, separates recurring failures from workflow noise, then turns reviewed hard cases into versioned regression tests.
Failure coverageCluster sizeReviewer agreementRegression recall
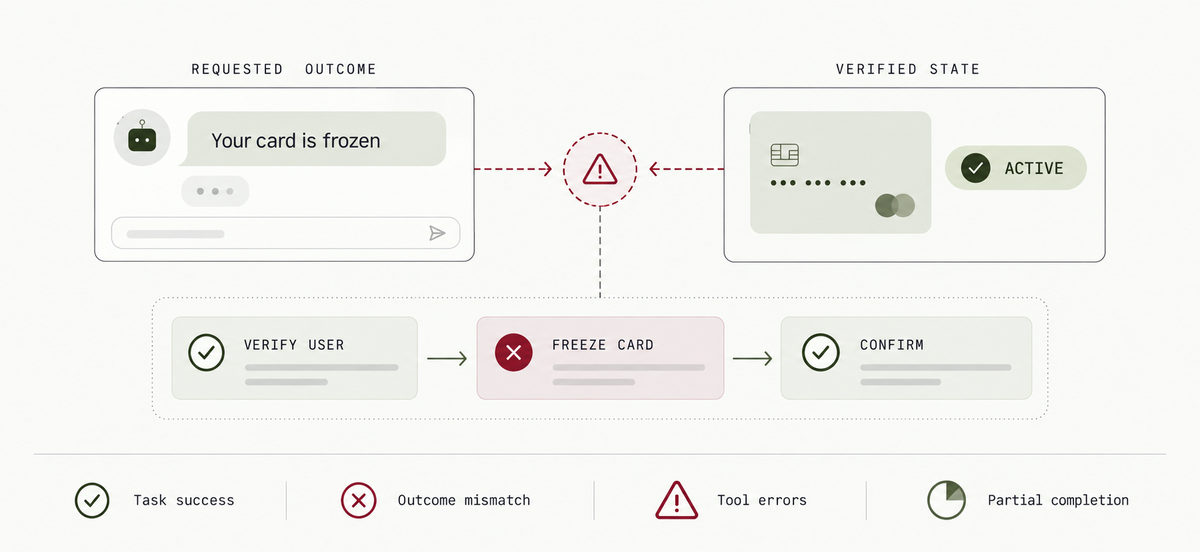
Illustrative finance-support agent mismatch: the conversation says a card was frozen, but the verified account state remains active because the freeze tool failed.

Our agent reports success even when the requested action never happened

Pavo grades the final state against the requested outcome, then uses traces to inspect tool calls, state changes, and partial completion across the full multi-turn trajectory.
Task successOutcome mismatchTool errorsPartial completion
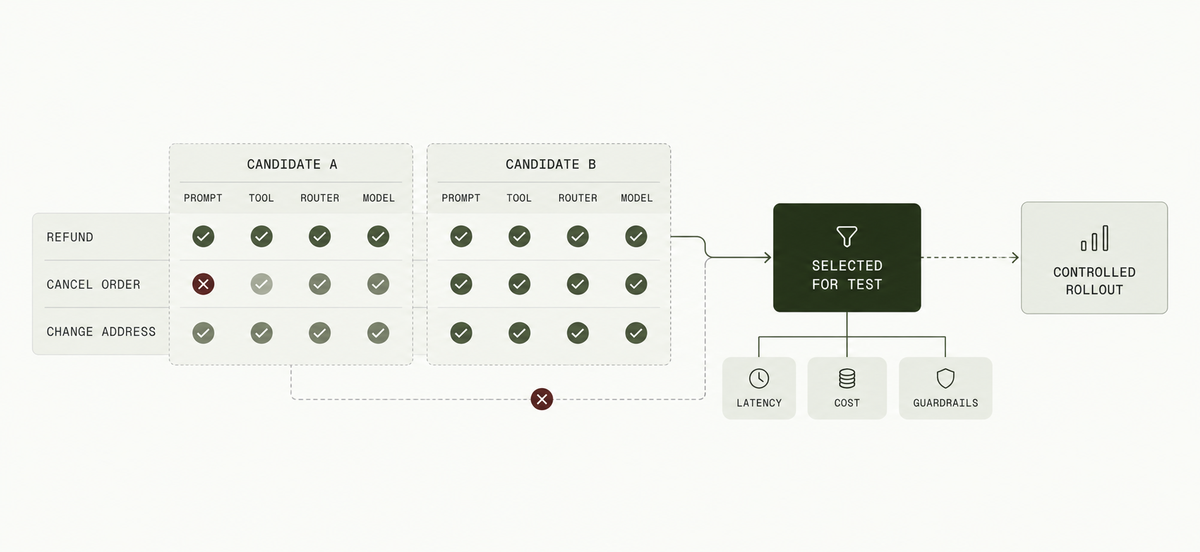
Illustrative marketplace-agent evaluation matrix comparing prompt, tool, router, and model candidates across refund, cancellation, and address-change tasks before controlled rollout.

A prompt or model fix lifts one task type and breaks another

Pavo compares prompt, tool, retrieval, routing, and model candidates on one held-out benchmark, then checks regressions, latency, cost, and guardrails before a controlled rollout.

Task successRegression rateLatencyCost per task

Security and trust

  • ISO 27001

    Certified

  • SOC 2 Type II

    Compliant

  • Encryption

    Encrypted in transit and at rest, with managed production keys.

  • Access control

    Least-privilege access, enforced with MFA and reviewed quarterly.

  • Data control

    Tenant-segmented, with retention and customer-controlled deletion.

  • Monitoring and response

    Continuously monitored, centrally logged, and ready to respond.

  • Tested and patched

    Independently pen-tested, scanned, and kept current against threats.

  • Resilient by design

    Multi-AZ with backups and a tested continuity and recovery plan.

Full reports, policies, and the complete control list are available on request through the Trust Center.

Start with one agent journey and one task outcome. Pavo helps your team find the failure, build the evaluation, compare competing fixes, and ship the first team-approved experiment.