Search ranking

The applied science factory for improving search ranking

Pavo learns how your search system works across queries, catalog, metrics, and experiment history. It finds opportunities, builds the evaluation, and runs experiments to keep moving the metric.

See how Pavo works

Current search stack

lexical · semantic · filters

Query signals

intent · context · reformulation

Catalog signals

content · availability · freshness

Rank + re-rank

500 → 50 candidates

Query-set evaluation

head · tail · zero-result

Controlled traffic

a slice of real queries

Search metric moves

Pavo learns your current search stack, reads query and catalog signals together to propose ranking changes, scores them against a held query set offline, runs the survivors on a slice of real traffic, and writes the measured result back.
  • Increase experimentation velocity

    Explore query understanding, retrieval, and ranking changes in parallel. Move stronger ideas to live tests faster.

  • Increase win rates

    Evaluate candidates across query cohorts and guardrails offline. Reserve live traffic for those with the strongest evidence.

  • Force multiplier for your team

    Automate query analysis, offline evaluation, and experiment preparation.

How it works

Connect your search stack

Connect code, queries, catalog data, metrics, and experiment history behind search.

Build system understanding

Pavo reconstructs how your production system works. Your team verifies the system book.

System bookArchitectureServices, models, pipelinesMetricsDefinitions and ownersFailure modesWhat breaks, and whenExperimentsPast runs and outcomes

Run applied science projects with Pavo

Give Pavo a metric goal. It frames the problem, spins up a project, runs analyses, explores interventions, and opens PRs.

Frame the problemBuild hypothesesRun interventionsEvaluate offlineLive A/B test

Capabilities

Applied science judgement

Picking the right problem, the right approach, the right lever

  • Finds where the metric is stuck - which surface, which query cohort: head or tail, navigational or broad
  • Knows whether to fix query understanding, retrieval, the ranker, or the objective
  • Grounds it in your own past experiments and search behaviour, not just what's in the repo
SEARCH SUCCESS · EXAMPLE8%WEBAPPHEADNEWTAILRETRIEVALTAIL RECALL GAPQUERYRANKEROBJECTIVEIMPROVE HYBRID RETRIEVALFOR TAIL QUERIES IN APPTest: search task successQUERY LOGSPAST EXPERIMENTS

Scientific rigour

Explores widely, and ships only what's proven

  • Tries lexical, dense, and hybrid retrieval, listwise rankers, query rewrites, and new objectives at once
  • You see which strategies win on replayed queries, before spending live search traffic
  • Corrects for position and exposure bias, and checks zero-result, long-tail, and new-item queries separately
REUSEDIMPROVE HYBRID RETRIEVALFOR TAIL QUERIES IN APPQUERY REPLAYPOSITION ADJ.QUERY COHORTS301031LEXICALDENSEHYBRIDQUERY REWRITERE-RANKERHEADNEWTAILDENSE ONLYHYBRID RRFHYBRID + RE-RANKSELECTEDTAIL-AWARE HYBRIDEXAMPLE · READY TO TEST

Knowledge compounds

Every iteration makes the next one cheaper

  • The work itself produces new knowledge - how people search, how well offline predicts online, which retrieval and ranking levers fail
  • Written back to your system book, reviewed by your team, reused next time - it stays with you
  • Your team owns the learnings, so v2 to v3 to v4 gets faster, not just further
01LEARN02RETAIN03REUSETail-aware hybridEXAMPLE · TESTEDHybrid restores tail recallNDCG overstates task successDense-only misses exact termsYOUR SYSTEM BOOKQUERY PATTERNSMETRIC CALIBRATIONLEVER HISTORYTIME TO PROOF · EXAMPLE4wV23wV31wV4KNOWLEDGE REUSED

Use-cases

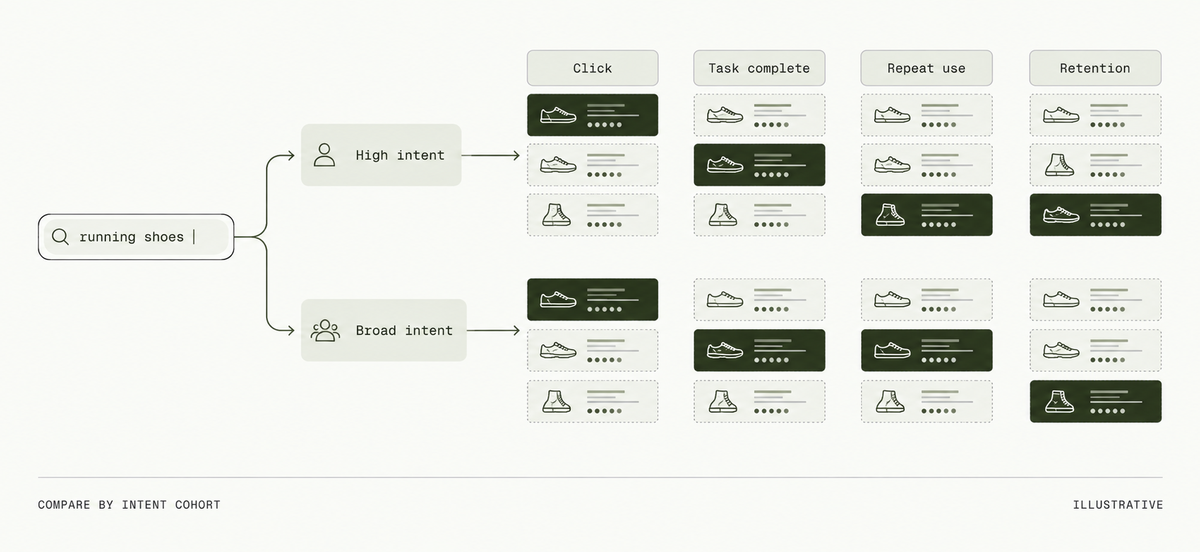
Illustrative marketplace search evaluation comparing click, task-completion, repeat-use, and retention objectives across high-intent and broad-intent running-shoe queries.

Our click-optimised search sends high-intent users to results that fail their task

Pavo compares click, task-completion, repeat-use, and retention objectives, then measures how each ranking policy performs across high- and low-intent queries.
CTRTask completionRepeat useRetention
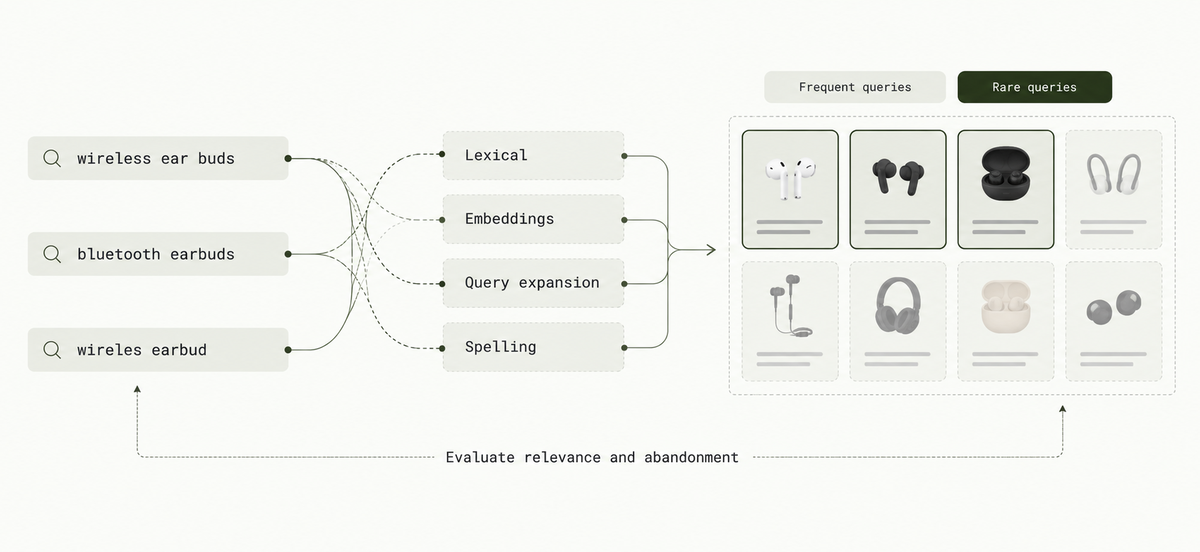
Illustrative hybrid retrieval flow: misspelled and synonymous marketplace queries converge on the same outdoor-jacket intent and recover relevant results.

Users express the same intent in different words, fragmenting recall on rare queries

Pavo tests lexical retrieval, dense embeddings, query expansion, and spelling correction, then measures relevance and abandonment across query-frequency cohorts.
RecallRelevanceAbandonmentQuery frequency
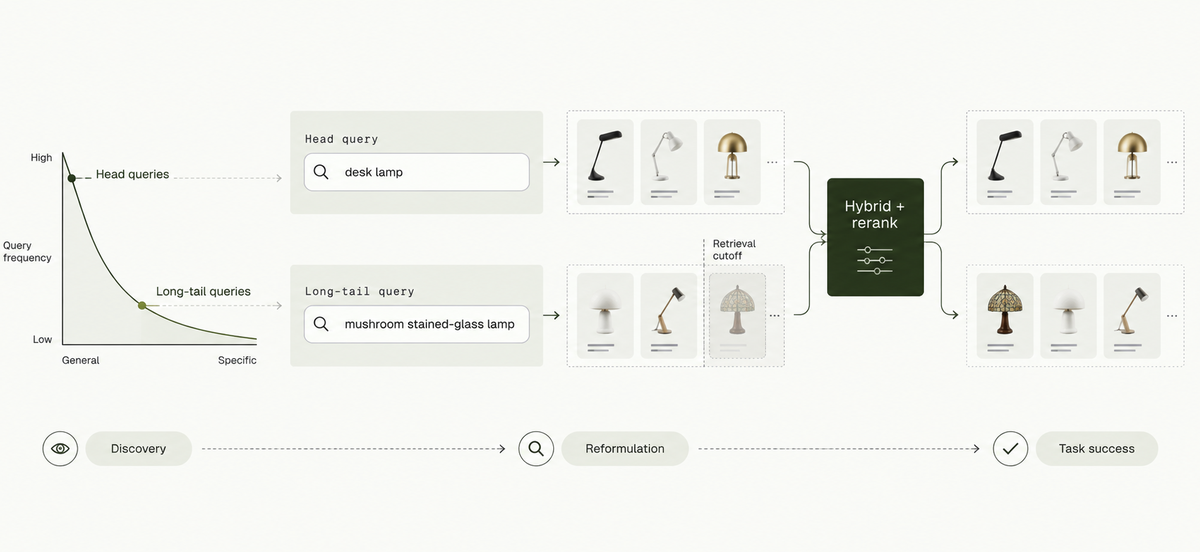
Illustrative marketplace long-tail search: hybrid retrieval and reranking surface a new mushroom-lamp listing for a rare query instead of only popular head-query items.

Our head queries improve while long-tail queries and new entities stay hard to find

Pavo segments queries by frequency and entity age, compares hybrid retrieval and reranking strategies, then tracks discovery, reformulation, and task success.

DiscoveryReformulationTask successLong-tail recall

Security and trust

  • ISO 27001

    Certified

  • SOC 2 Type II

    Compliant

  • Encryption

    Encrypted in transit and at rest, with managed production keys.

  • Access control

    Least-privilege access, enforced with MFA and reviewed quarterly.

  • Data control

    Tenant-segmented, with retention and customer-controlled deletion.

  • Monitoring and response

    Continuously monitored, centrally logged, and ready to respond.

  • Tested and patched

    Independently pen-tested, scanned, and kept current against threats.

  • Resilient by design

    Multi-AZ with backups and a tested continuity and recovery plan.

Full reports, policies, and the complete control list are available on request through the Trust Center.

Start with one search surface and one metric. Pavo helps your team understand the system, evaluate better approaches, and ship the first qualified experiment.